Google DeepMind’s Resident Philosopher: Why AI Ethics Needs to Move Faster
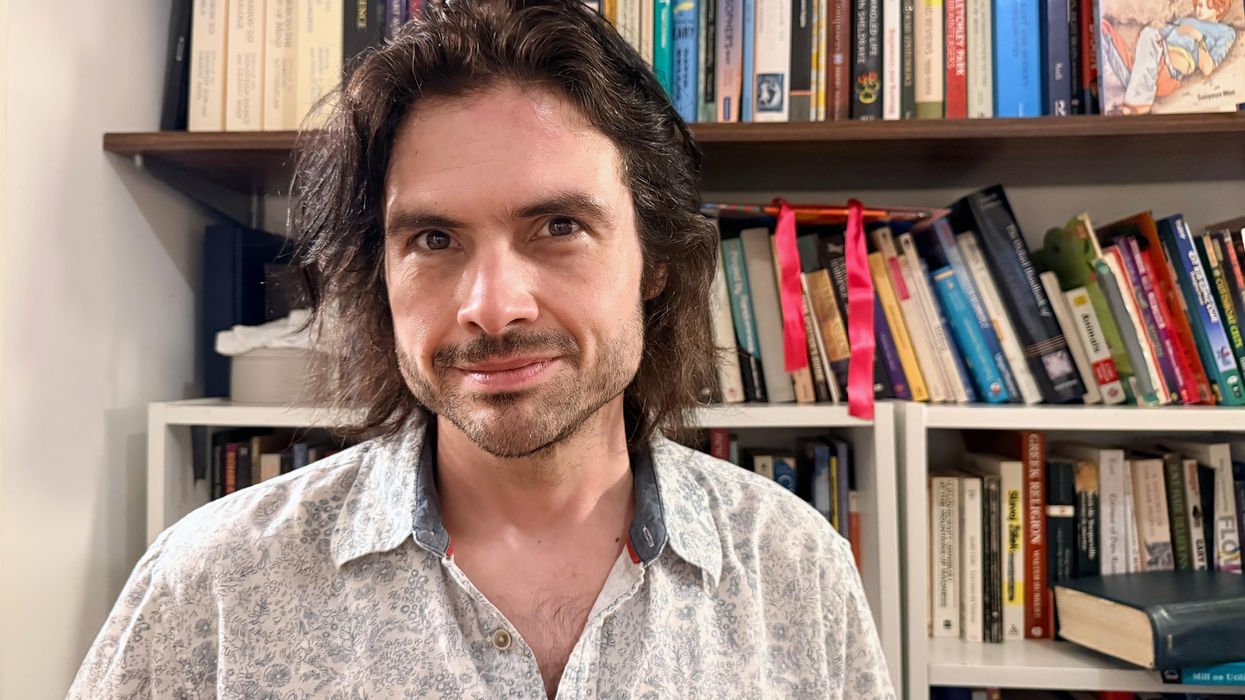
Henry Shevlin has a job title that would look strange on almost any org chart: Philosopher. Not “AI ethicist,” not “responsible AI lead,” not “policy advisor.” Philosopher, at Google DeepMind, where he now spends 80 percent of his time. The remaining 20 percent stays with Cambridge University’s Leverhulme Centre for the Future of Intelligence, where he remains active.
Shevlin joined the lab in May. His arrival is a small signal of something larger: the discipline that spent a decade critiquing AI from a safe distance is now being hired into the room where the models are built. And Shevlin’s own account of why he moved suggests the traffic runs mostly one way.
Why a Philosopher Would Leave Academia for an AI Lab
Shevlin gives four reasons, and none of them is money.
The first is people. Many of his most brilliant students came from DeepMind, which meant the lab already held a concentration of the kind of mind he liked teaching. The second is leverage. Shevlin says a lecture he gave at DeepMind led someone at a major financial institution to make organizational changes that he believes positively affected millions of people. That is an unusual sentence for a philosopher to be able to write about a single talk.
The third is cultural. Shevlin describes a deep commonality between DeepMind’s culture and the scientific attitude he favors, the disposition to test claims rather than defend positions. The fourth is the blunt one: AI labs are where high-quality philosophy and cognitive science are now taking place. Not “also taking place.” Taking place.
That claim will irritate plenty of people in humanities departments, but Shevlin is not arguing that philosophy has been captured by industry. He is arguing that the questions philosophy cares about, what a mind is, what understanding requires, what it means to reason, have become empirical questions that move at the speed of model releases. A department that meets monthly cannot keep pace with a system that changes quarterly.
Academia’s Slow Awakening
Shevlin is direct about his former field. Large parts of AI ethics academia, he says, were “quite slow to wake up” about what AI systems could actually do, and he describes academia as “sluggish” on the question.
His prescription is not more theory. It is contact. Shevlin argues that daily hands-on use of large language models is “basically essential” for developing good mental models of them, systems he calls “very weird things.” The word choice matters. Weird is a dismissal’s opposite. It is a claim that LLMs do not fit existing categories cleanly, and that people reasoning about them from secondhand summaries keep importing assumptions that the technology does not honor.
For engineers, the implication is uncomfortable in a useful way. Reading about a model’s behavior is not the same as building with it. The failure modes that matter, the ones that shape what a system can be trusted to do, tend to show up in the third week of a deployment, not in the abstract.
Debates That Expire
Some of the loudest arguments in AI discourse have not been resolved. They have been overtaken.
Shevlin points to early predictions that LLMs would “only produce beige, only produce slop,” a forecast that aged badly as models reached frontier-level performance in mathematics and coding, in some cases surpassing human ability. His conclusion is unambiguous: LLMs are “not stuck at the level of mediocre humanity.” He is careful to add a ceiling, though. They may never deliver “the Einstein moments, the Picasso moments.” But in some domains, he says, they are “really at the frontier.”
That is a more interesting position than either camp usually allows. It rejects the dismissal of LLMs as stochastic parlor tricks without accepting that they will inevitably become geniuses. The honest framing is domain-specific: extraordinary at some things, ordinary at others, and not obviously on a trajectory toward the most dramatic forms of human creativity.
The research literature has been tracking this shift for a while, and much of it lands first on preprint servers. For anyone trying to follow where the field’s claims are coming from, the infrastructure is worth understanding, from why the arXiv cs.AI listing page is a daily feed for applied AI engineers to what arXivLabs actually does.
Slop, Dialect, and the Craft of Prompting
Shevlin draws a distinction that gets flattened in most complaints about AI writing. There is content slop, meaning output that is empty of substance, and there is LLM-style language, which is a different thing entirely and gets the same insult.
On substance, he is bullish. The conceptual content of LLM outputs has improved dramatically, and he says that in the right context a model can discuss philosophy at a level associated with some of his best graduate students. On style, he is more clinical. He identifies a distinctive “LLM dialect” with telltale vocabulary: “genuinely,” “delve,” “load-bearing.” These are not failures of reasoning. They are tics, and Shevlin notes they are easy to avoid with the right prompting and that they change with every model generation.
That last point deserves emphasis for anyone building products on top of these systems. A prompt that strips the dialect today may not strip it in six months, because the dialect itself is a moving target. Style control is a maintenance task, not a one-time fix.
Shevlin also cites a paper by Murray Shanahan and Catherine Clarke on using LLMs for creative fiction. Their finding: adjusting the temperature variable to make outputs less predictable produces what amounts to James Joyce – style fiction. The takeaway is not that models write like Joyce by default. It is that the sampling parameters are a creative control surface, and treating temperature as a mere reliability dial undersells what it does.
Autonomy: Not All or Nothing
Asked whether it is better to make AI systems good or to curb their autonomy, Shevlin refuses the framing. Getting the safety question right matters enormously, he says, but he rejects the position that agents should never be used at all. That stance, in his words, “would be too strong.”
His examples are practical rather than dramatic. Agents taking on tedious work so people can spend time on creative labor. Agents streamlining processes in medical research, where administrative overhead consumes time that could go to science. Neither is a utopian pitch. Both are the kind of incremental delegation that already happens with ordinary software.
And Shevlin practices what he argues. He says he has taken Waymos “very happily many times now” and calls them “fantastic.” Waymo is a robotaxi service that operates in selected US cities. A philosopher of mind publicly endorsing a deployed autonomous vehicle is a small data point, but it is a concrete one. The autonomy debate is not hypothetical anymore. It is a question about specific systems in specific contexts, with specific failure rates, and the answer will differ by domain.
How a System’s Self-Description Shapes Trust
One thread from the source material remains unresolved, cutting off mid-sentence during a section on scholars who object to AI systems referring to themselves as “I,” preferring that they present themselves as marketplaces or something similar. The substance is worth flagging even without the full argument: the grammar a system uses to describe itself shapes how users attribute agency to it, which in turn shapes what they trust it to do.
What Shevlin’s move does establish is a direction of travel. The philosopher is no longer outside the lab writing commentary. He is inside it, on an 80 percent schedule, arguing that the people closest to the technology are best positioned to think clearly about it, and that the academic timeline is now the slower one.
For engineers building and deploying LLM-based systems, that reframes a few familiar tasks. Prompting deserves attention as a style-control surface, because dialect is controllable and will drift. Temperature governs how surprising the output can be, which makes it a creative setting as much as a reliability one. Autonomy is a question of degree: which tasks, under what supervision, at what failure cost. And keeping up with the field means reading claims in their original form, on the servers where they first appear, rather than waiting for the summary that arrives two years late.
The uncomfortable part of Shevlin’s argument is not that AI labs do good philosophy. It is that the rest of us may be reasoning about these systems with mental models that were accurate eighteen months ago and are not accurate now.